Introducing Datenrösterei
Roughly 3,100 lines of field-tested SAP Datasphere and SAC planning reference, plus a billion-row ABAP table exporter, now public on GitHub.
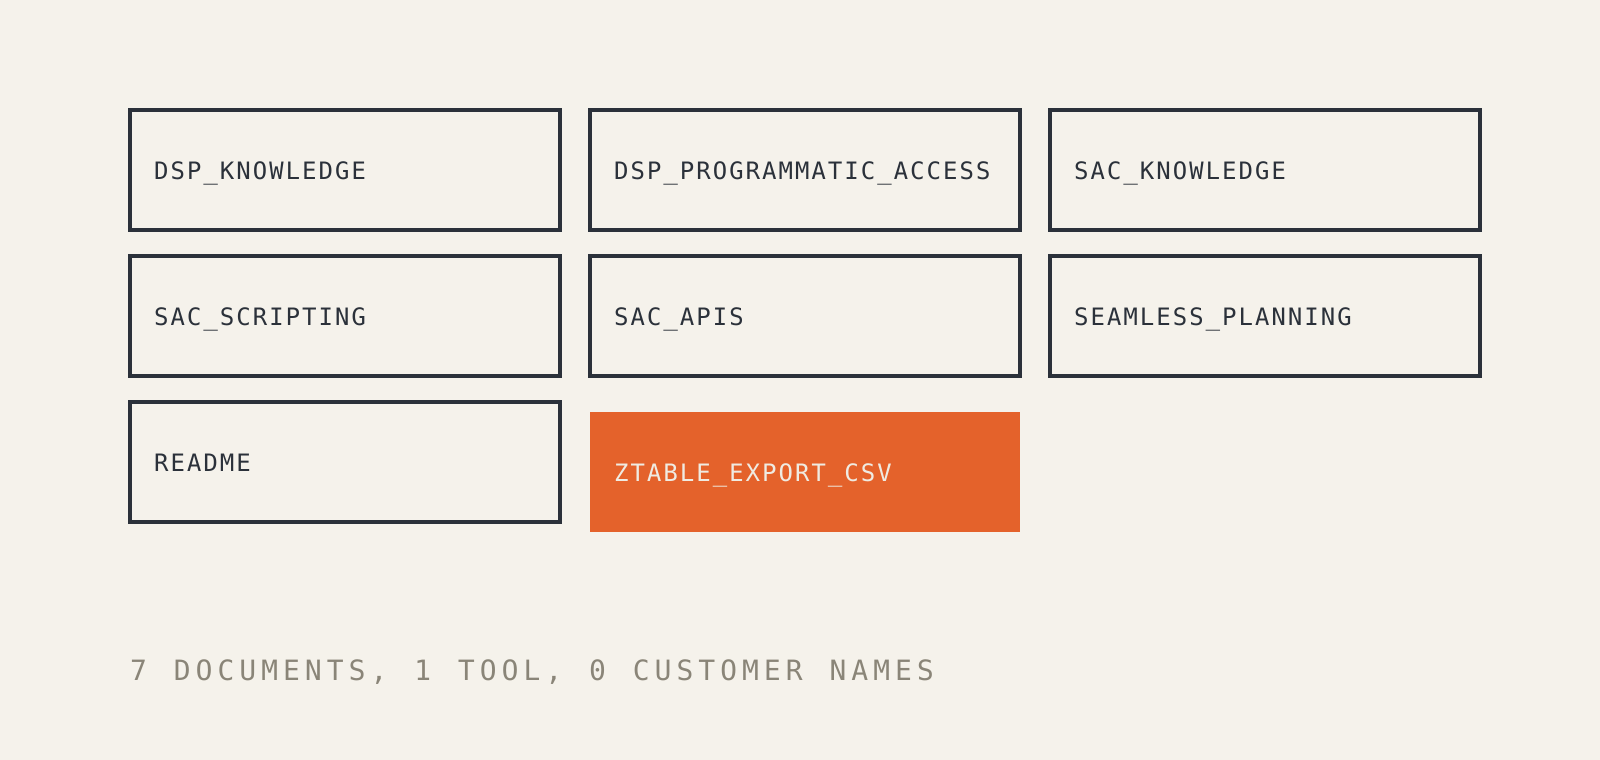
Datenrösterei is now public: roughly 3,100 lines of working reference on SAP Datasphere and SAC planning in seven documents, plus a production ABAP report that exports billion-row tables to CSV without falling over. All of it from productive project work. All of it generalised — no customers, no tenants, no identifiers that mean anything outside a placeholder.
Why publish internal notes
The official documentation is large and mostly accurate. That's not the gap. The gap is that official documentation describes what features do when they work, and nearly all the expensive time on a real project goes to things that fail without saying so: the HTTP 200 that's actually an HTML login page, the green data action that wrote nothing, the export that's missing every row past a page cap, the import with zero rejects that collapsed rows anyway.
None of these throw. All of them cost days the first time and minutes every time after — if someone wrote the first encounter down. These notes are those write-downs. They existed anyway; publishing cost little. The alternative is every team paying the same days independently, which is the actual state of the SAP ecosystem, and it annoys me.
The name: a Rösterei is a roastery. Raw beans aren't a drink and raw tables aren't a model — someone has to apply heat carefully and know when to stop. That's the whole metaphor, and I'll leave it there.
What's in it
| Document | One line |
|---|---|
DSP_KNOWLEDGE.md |
Datasphere modelling: layer architecture, view patterns, HANA quirks inside DSP, persistence lifecycle, cross-space rules |
DSP_PROGRAMMATIC_ACCESS.md |
Automation: the OAuth identity model (the fact that decides feasibility), CLI, OData, Open SQL Schema, task chains |
SAC_KNOWLEDGE.md |
Planning: the Advanced Formulas execution model, parameter traps, version handling, allocation edge cases |
SAC_SCRIPTING.md |
Story scripting: bindings, inherited context, the migration checklists |
SAC_APIS.md |
Import/export APIs, Data Export Service paging, InA — where "complete" isn't |
SEAMLESS_PLANNING.md |
The inverted binding: SAC provisions tables inside the Datasphere space |
README.md |
How to read the rest, and the epistemic rules |
The epistemic rules matter more than any single entry: every claim is marked as documented behaviour or field observation. A measured limit from last year is a rumour today. A note that doesn't tell you which kind of claim it's making is a note you can't safely reuse.
The ABAP report
ZTABLE_EXPORT_CSV gets ACDOCA-class tables out of an SAP system in one piece: streaming cursor, chunked CSV, resume via keyset pagination. Constant memory at any row count, MIT licensed, one source file. The design decisions and the measurements are their own article — including the part where the profiler disagreed with my intuition about where the time goes.
If you find something that's wrong — or has rotted — open an issue. Observed behaviour changes quarterly. That's the deal with field notes, and pretending otherwise would make them worthless.
The documents and source code behind this entry are published in full — generalised and openly licensed — in Datenrösterei. Corrections and additions welcome as an issue or a pull request.